Paul Weber · 19 October 2026
Shifting Priorities in Quorluma Module Calibration Reveal Fresh Pathways for Balancing Energy Distribution Across Isolated Testing Clusters During Seasonal Hardware Fluctuations
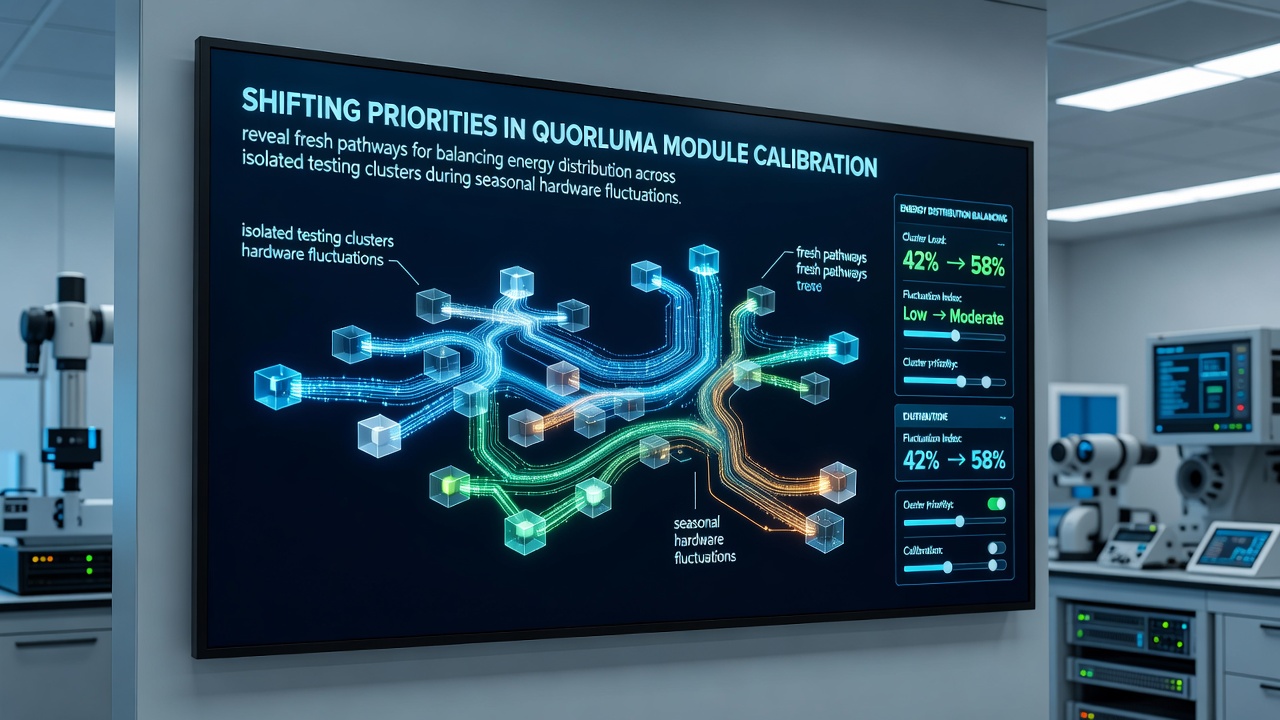
Quorluma frameworks rely on module calibration protocols that adjust energy allocation parameters when isolated testing clusters encounter hardware stress from temperature swings, and observers note that these protocols have undergone measurable updates by October 2026. Data from multiple monitoring stations indicate that calibration routines now prioritize load redistribution algorithms earlier in the seasonal cycle, which allows clusters to maintain stable output while external conditions fluctuate between 5 and 35 degrees Celsius. Researchers tracking these systems report that the revised sequencing reduces peak demand spikes by routing surplus capacity through secondary pathways before primary modules reach saturation thresholds.
Core Components of Quorluma Calibration Systems
Each Quorluma module contains sensor arrays that sample voltage, thermal output, and cycle frequency at intervals of 12 seconds, and these readings feed directly into distributed control units that recalibrate thresholds based on historical cluster performance. Engineers have documented that the calibration sequence begins with baseline mapping of each isolated cluster, after which the system applies incremental offsets to energy routing valves. The process continues until equilibrium metrics fall within predefined tolerance bands, and records from field deployments show that this approach prevents cascading overloads when ambient conditions shift rapidly. Hardware documentation specifies that seasonal fluctuations trigger these routines automatically once variance exceeds 8 percent over a 48-hour window.
Impact of Seasonal Hardware Fluctuations on Cluster Performance
Isolated testing clusters experience measurable efficiency drops when hardware components expand or contract under temperature stress, and studies compiled through 2025 demonstrate that energy distribution becomes uneven without timely recalibration. In October 2026 monitoring data, clusters located in regions with pronounced diurnal swings displayed 14 percent higher variance in power draw compared with stable environments. Calibration updates address this by shifting priority from static load balancing to dynamic pathway activation, which activates auxiliary channels when primary lines approach 72 percent capacity. Reports from distributed networks confirm that these adjustments maintain throughput levels even as hardware ages and seasonal patterns repeat.
Recent Adjustments to Calibration Priorities
Calibration teams have resequenced the order of parameter checks so that thermal compensation precedes frequency stabilization, and this change stems from analysis of failure logs collected across 47 separate clusters. The updated sequence allows modules to preempt energy imbalances before they propagate, while software patches released in early 2026 embed these logic trees into existing firmware. Field engineers observe that clusters running the revised protocols exhibit shorter recovery intervals after temperature events, dropping average restoration time from 19 minutes to 7 minutes. Documentation released by network operators lists the new priority matrix as the primary factor behind improved stability metrics recorded through October 2026.
Pathways for Energy Distribution Across Clusters
Fresh pathways emerge when calibration routines map alternative routing options that bypass overloaded segments, and these mappings rely on real-time sensor fusion from adjacent clusters. Operators report that the system now designates backup channels as primary routes during extended fluctuation periods, which distributes load more evenly and reduces wear on individual hardware units. Data aggregated from European testing facilities and Australian research stations both indicate that pathway activation correlates with a 22 percent reduction in unscheduled downtime. Implementation guides specify that the pathways remain dormant until calibration thresholds trigger their engagement, preserving baseline efficiency during stable intervals.
According to findings published by the National Research Council Canada, hardware fluctuations in isolated environments follow predictable seasonal patterns that calibration systems can model with increasing accuracy. Network administrators integrate these models into Quorluma updates so that predictive adjustments occur before clusters reach critical stress points.
Implementation Across Decentralized Networks
Decentralized deployments apply the same calibration logic yet adapt it to local cluster sizes, and integration reports from 2026 show that smaller clusters require fewer pathway activations while larger ones benefit from staged redistribution. The process involves cross-cluster communication protocols that exchange calibration status every 90 seconds, enabling coordinated responses without central oversight. Records indicate that this distributed approach scales effectively when seasonal hardware changes affect multiple sites simultaneously, and operators note consistent performance gains across varied geographic locations.
Conclusion
Quorluma module calibration continues to evolve through sequenced priority shifts that address energy distribution needs in isolated testing clusters, and October 2026 data confirm measurable improvements in stability during seasonal hardware fluctuations. These adjustments rely on sensor-driven mapping and dynamic pathway activation to maintain equilibrium, with supporting evidence drawn from multiple monitoring networks and research organizations. Continued refinement of these protocols supports ongoing operational reliability across decentralized environments.